
Availability & Failover
Watched 24/7, failed over before your customers notice.
Managed cloud →
Managed cloud operations on infrastructure we run across the US, Europe, and Asia. We build, we run, and we answer for the outcome.
A working session on your architecture. You leave with a clear read of your failure modes and recovery posture.
Built on technologies trusted in production worldwide
We run our own cloud, operate what runs on it, and stay accountable from the infrastructure layer through release. One operator, one line of accountability, measured in the outcomes we deliver.
Dedicated infrastructure across facilities in the US, Europe, and Asia, with data residency by region.
US · EU · Asia
Built with your engineers or ours, and the monitoring, patching, drills, and response stay with us.
Apps · APIs · modernization
A P1 to P4 severity model, defined change management, and a post-incident report after every incident.
P1 to P4 · SLAs on request
Availability & Failover
Watched 24/7, failed over before your customers notice.
Managed cloud →Resilience & DR
Recovery rehearsed on a schedule, never assumed.
Disaster recovery →DevOps Delivery
Gated, canaried, rolled back automatically.
DevOps →AI Operations
AI accelerates; engineers approve every action.
AI agents →What owning them means
In every package
99.9% infrastructure uptime as our operating standard, with monitoring around the clock and every alert severity-graded P1-P4.
Proof · the portal, live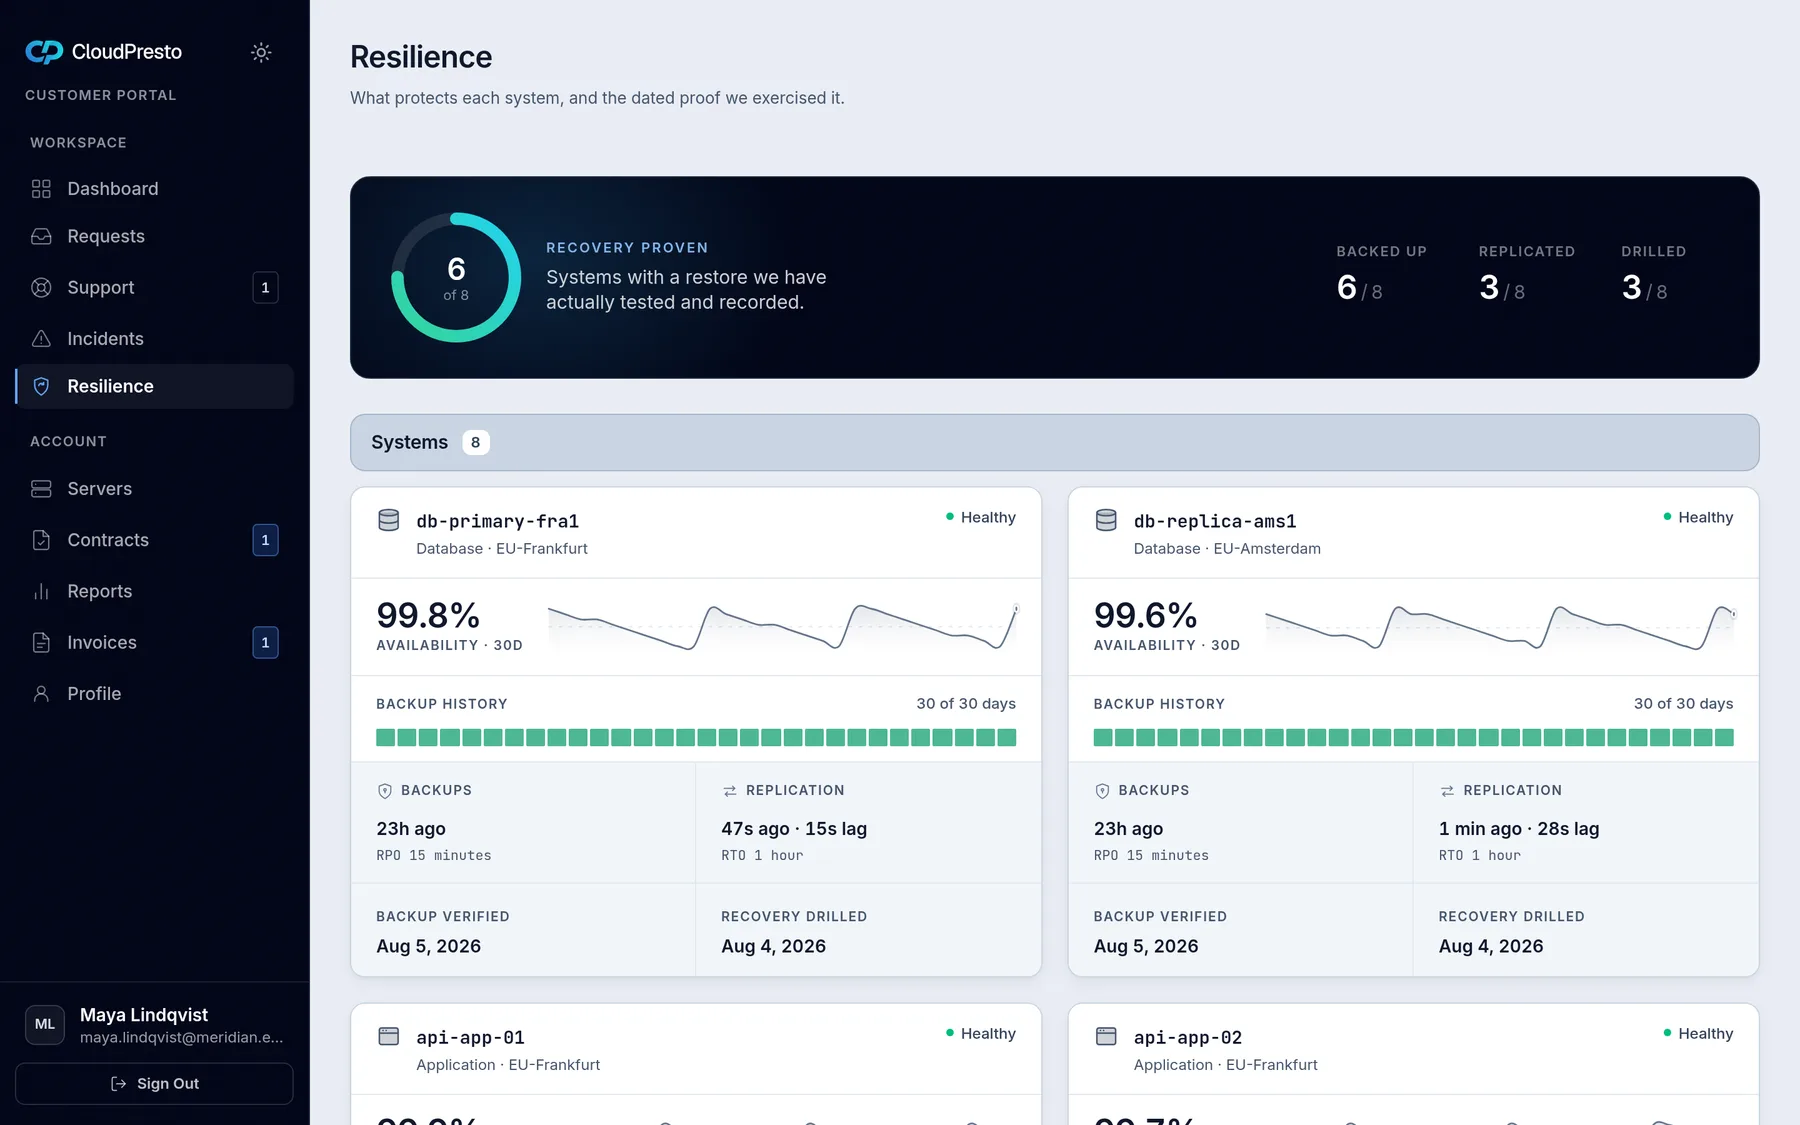
In every package
Recovery objectives engineered per tier and proven in scheduled drills, with RTO under 15 minutes for mission-critical workloads, on the 3-2-1+1 backup floor below.
Proof · a drill record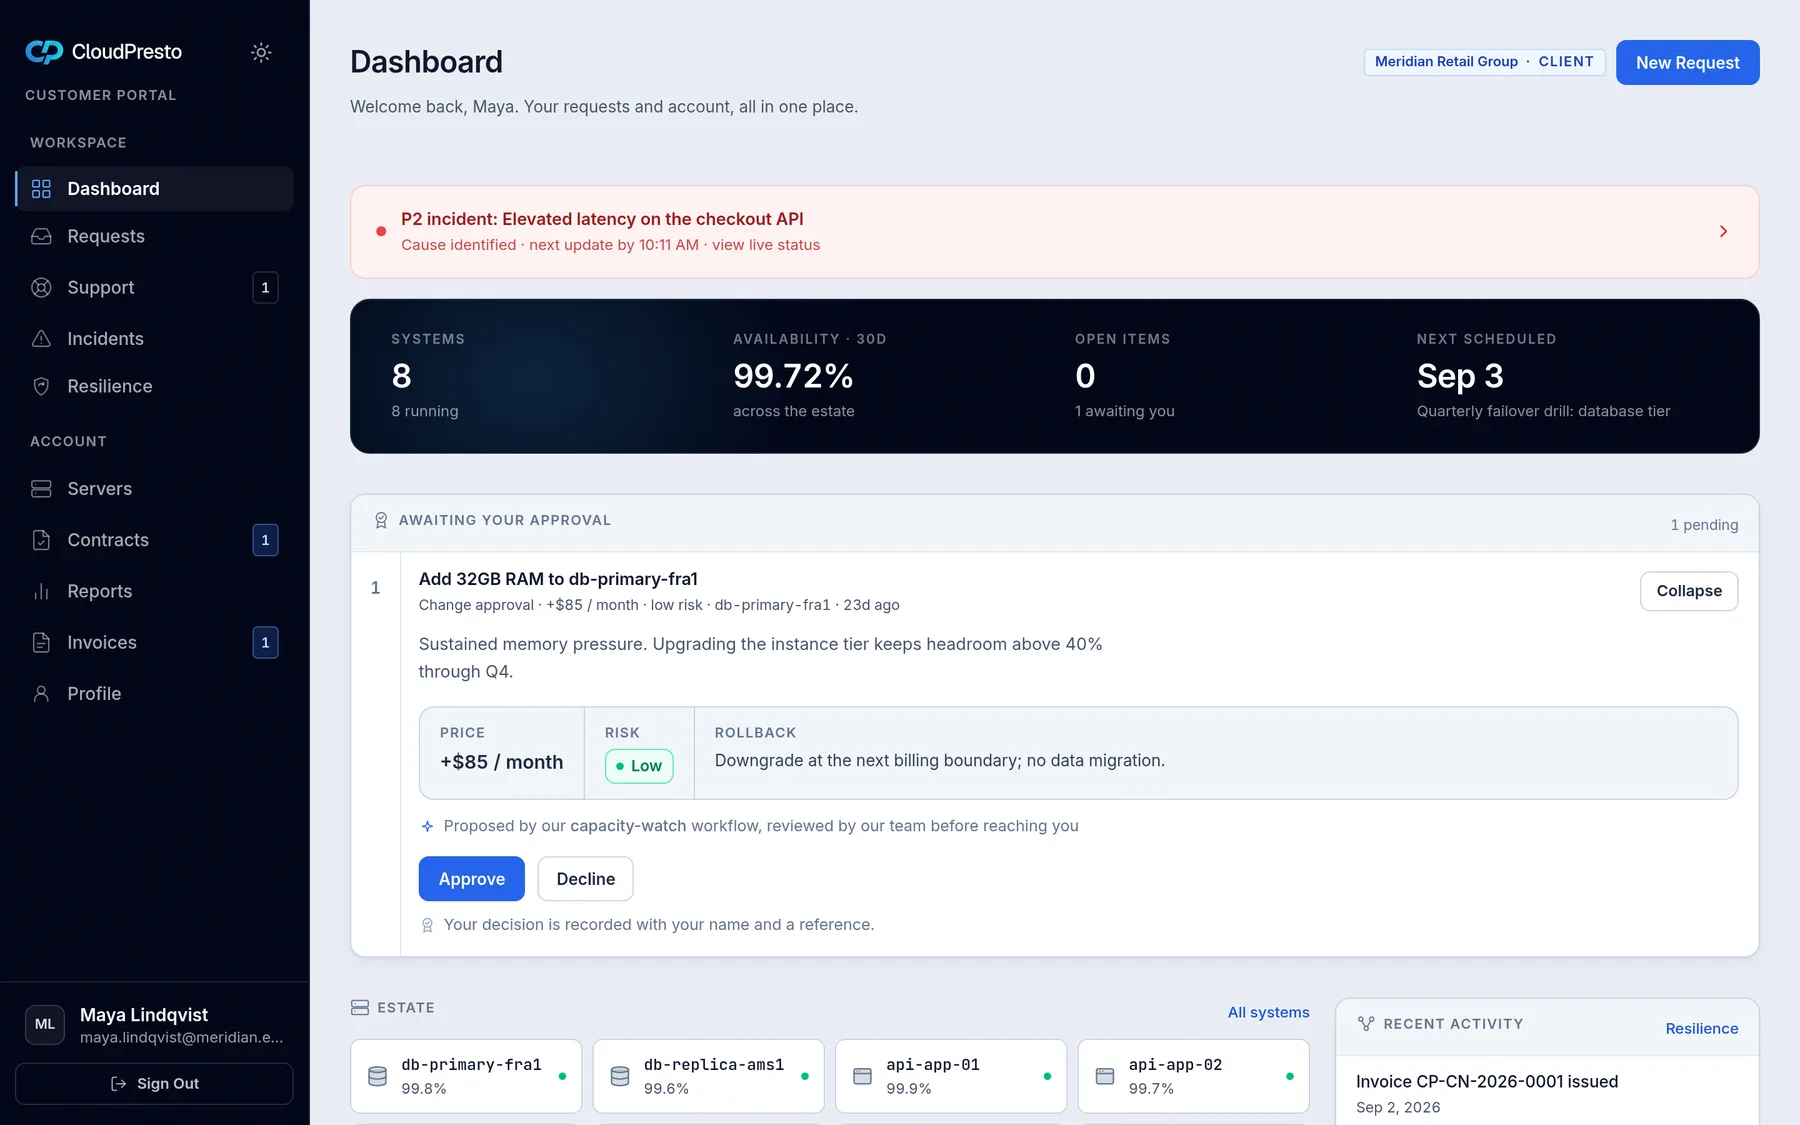
In every package
Promotion gates, canary releases, and automated rollback carry every change, with DevOps engineering hours part of the service.
Proof · the pipeline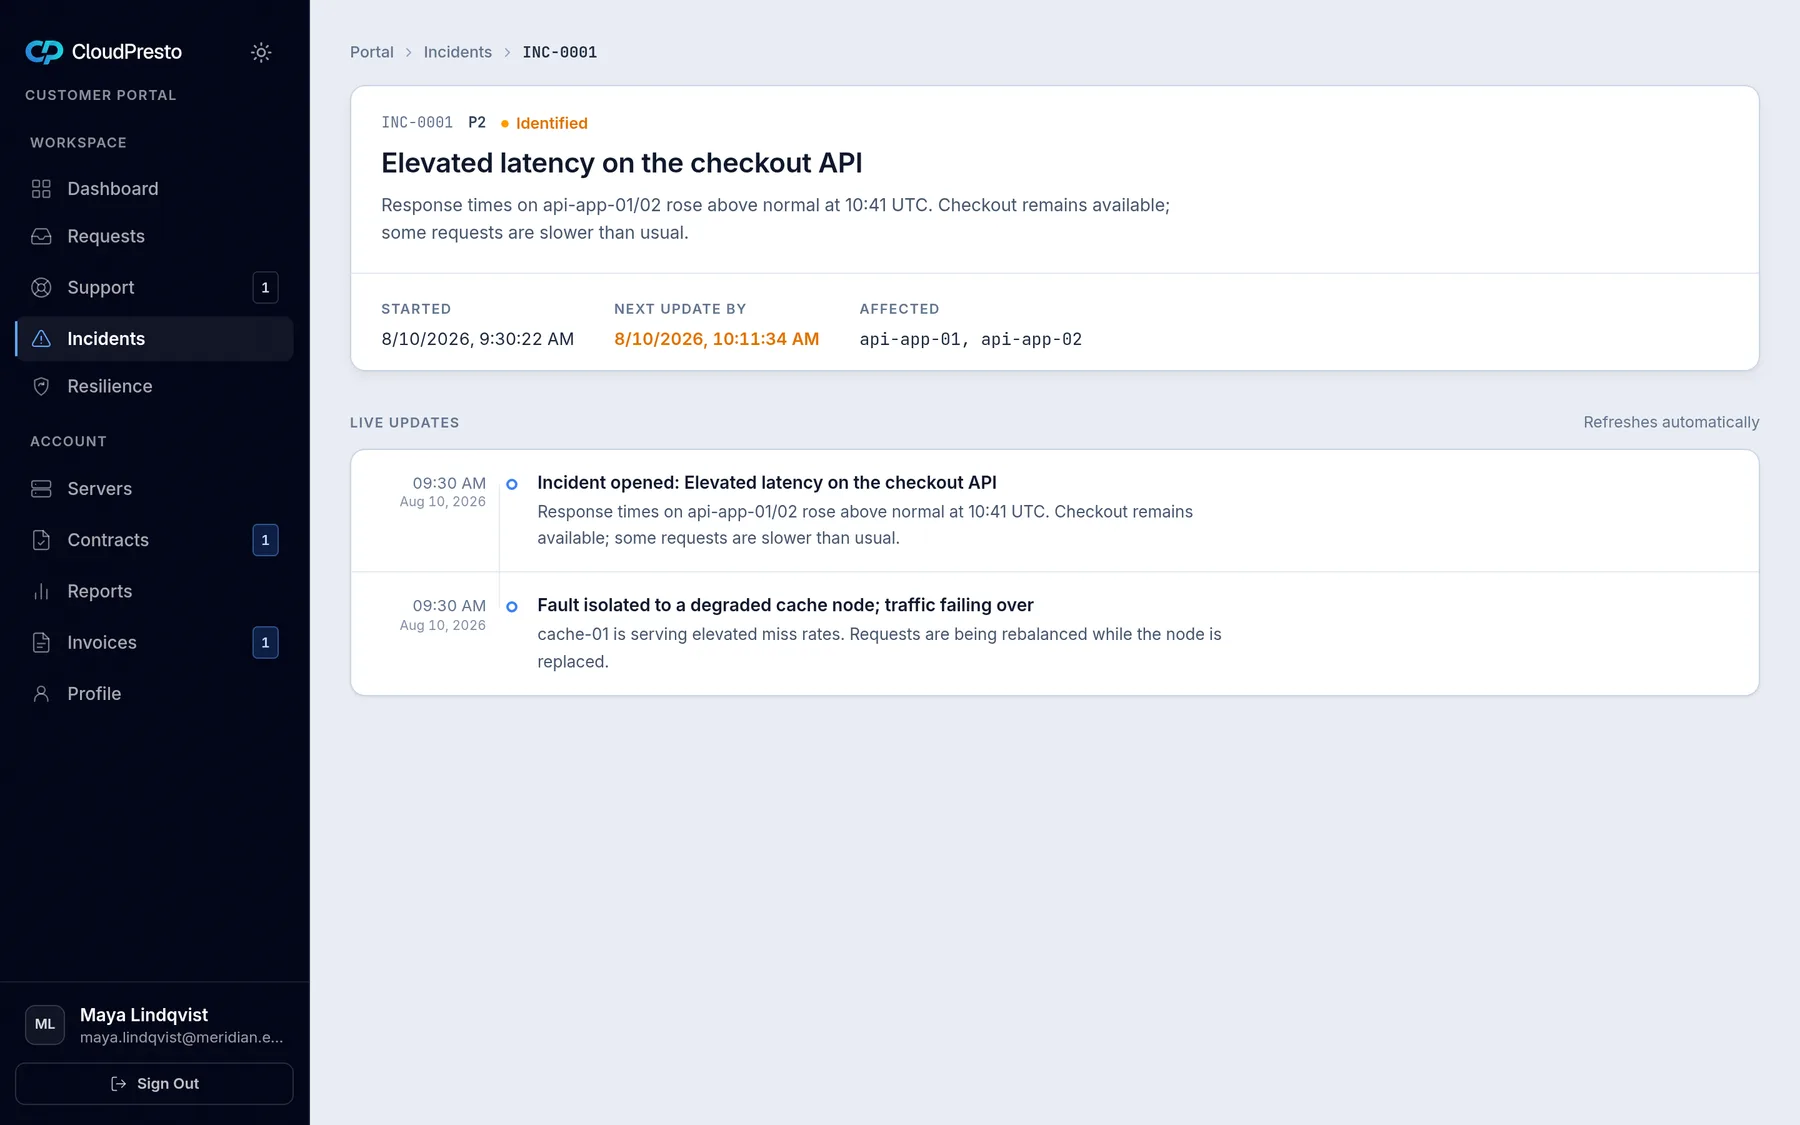
In every package
Cause found, fix shipped through change management, and the whole timeline recorded on the incident in your portal.
Proof · an incident, end to endWhat building it means
Scoped engagement
Scope and architecture set with you first: web applications, APIs and integrations, mobile, modernization.
See how we build
Scoped engagement
Built in increments and shipped through the same guardrails as everything on the line: gates, canary, rollback.
See the pipeline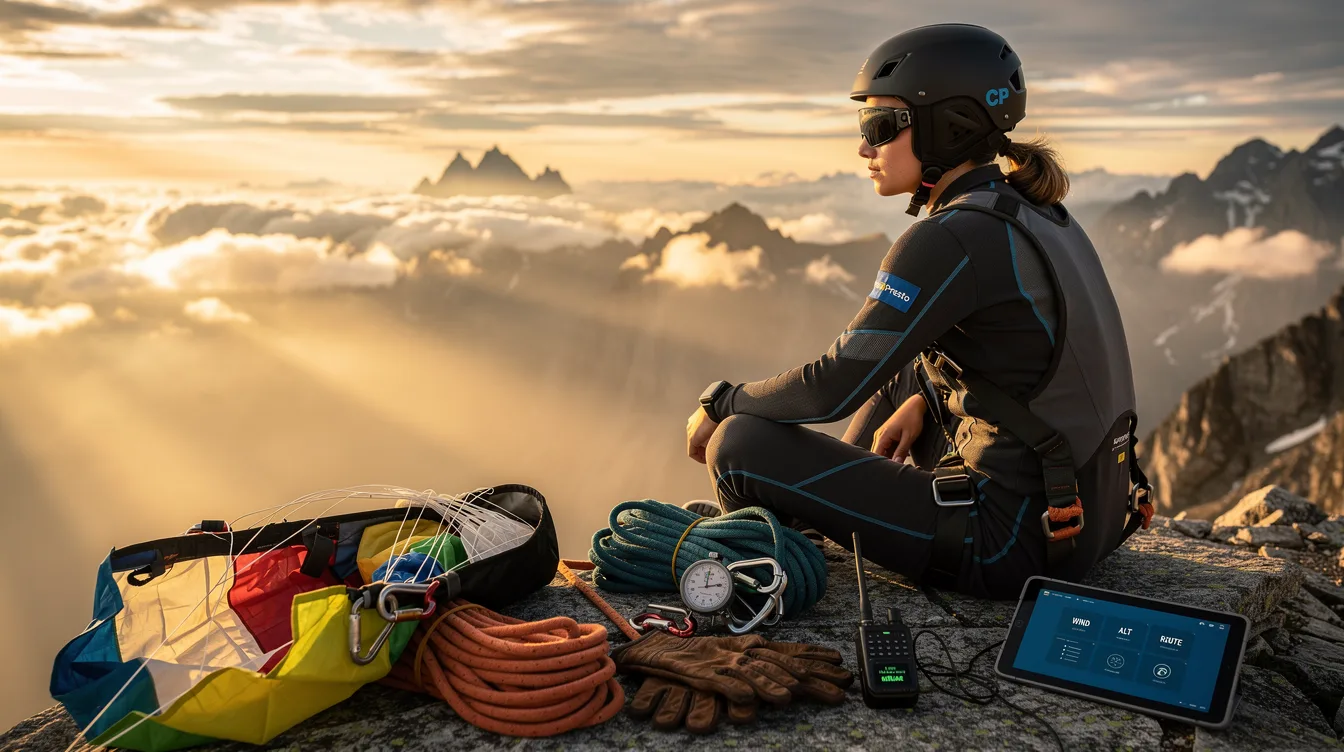
Scoped engagement
Instrumented from the first commit, then handed straight into the pipeline, the runtime, and the ops loop.
See the runtime
Scoped engagement
Per-project, retainer, or a dedicated team, and the operations stay with us either way.
Engagement modelsSix ship in every package. Three scope to your engagement.
01 · Security
Contained by design, accountable by record.
AES-256 · TLS 1.3 · MFA + SSO
02 · Backups
Three copies, two systems, one offsite, plus one on another continent.
3-2-1+1 · restore-verified
03 · Compliance
Controls aligned with SOC 2, ISO 27001, and CIS.
SOC 2 · ISO 27001 · CIS aligned
04 · Operations
Watched around the clock. Every alert graded P1-P4, P1 escalated immediately.
24/7 · P1-P4 · 99.9% uptime standard
05 · Resilience
Recovery objectives engineered per tier and proven in scheduled drills.
RTO < 15 min · quarterly drills
06 · Delivery
Gated, canaried, rolled back automatically. Engineering hours included.
gates · canary · rollback
07 · AI
AI assists our operations in every package. Agents for your business are scoped with you.
supervised · audited · change-controlled
08 · Build
Bring an idea. We build it with you, then run it.
per-project · retainer · dedicated team
09 · Migration
Move onto infrastructure we run, with the cutover rehearsed first.
phased · parallel-run · reversible
Artifacts from the way we actually work: the drill record, the shipping portal on our demo estate, and a product we built and run.
Case file
4 exhibits
Exhibit A · The drill record
Every drill runs on a schedule against production-shaped infrastructure and produces this record, with your measured numbers in it.
drill-record_cross-region-failover.md
01# Quarterly failover drill · scheduled
02Scope: primary region loss, full estate
03Objective: recovery within contracted RTO
04T+0:00 primary region isolated (induced)
05T+0:0X [measured] monitoring pages, severity graded P1
06T+0:0X [measured] runbook DR-04 invoked, failover begins
07T+0:0X [measured] traffic served from standby region
08T+0:XX [measured] data verified against RPO
09Findings: what was slow, who owns the fix
10Next drill: [date] · set in the retro
71%
of organizations do no failover testing at all.
Cockroach Labs, State of Resilience 2025 (Wakefield Research, n=1,000)
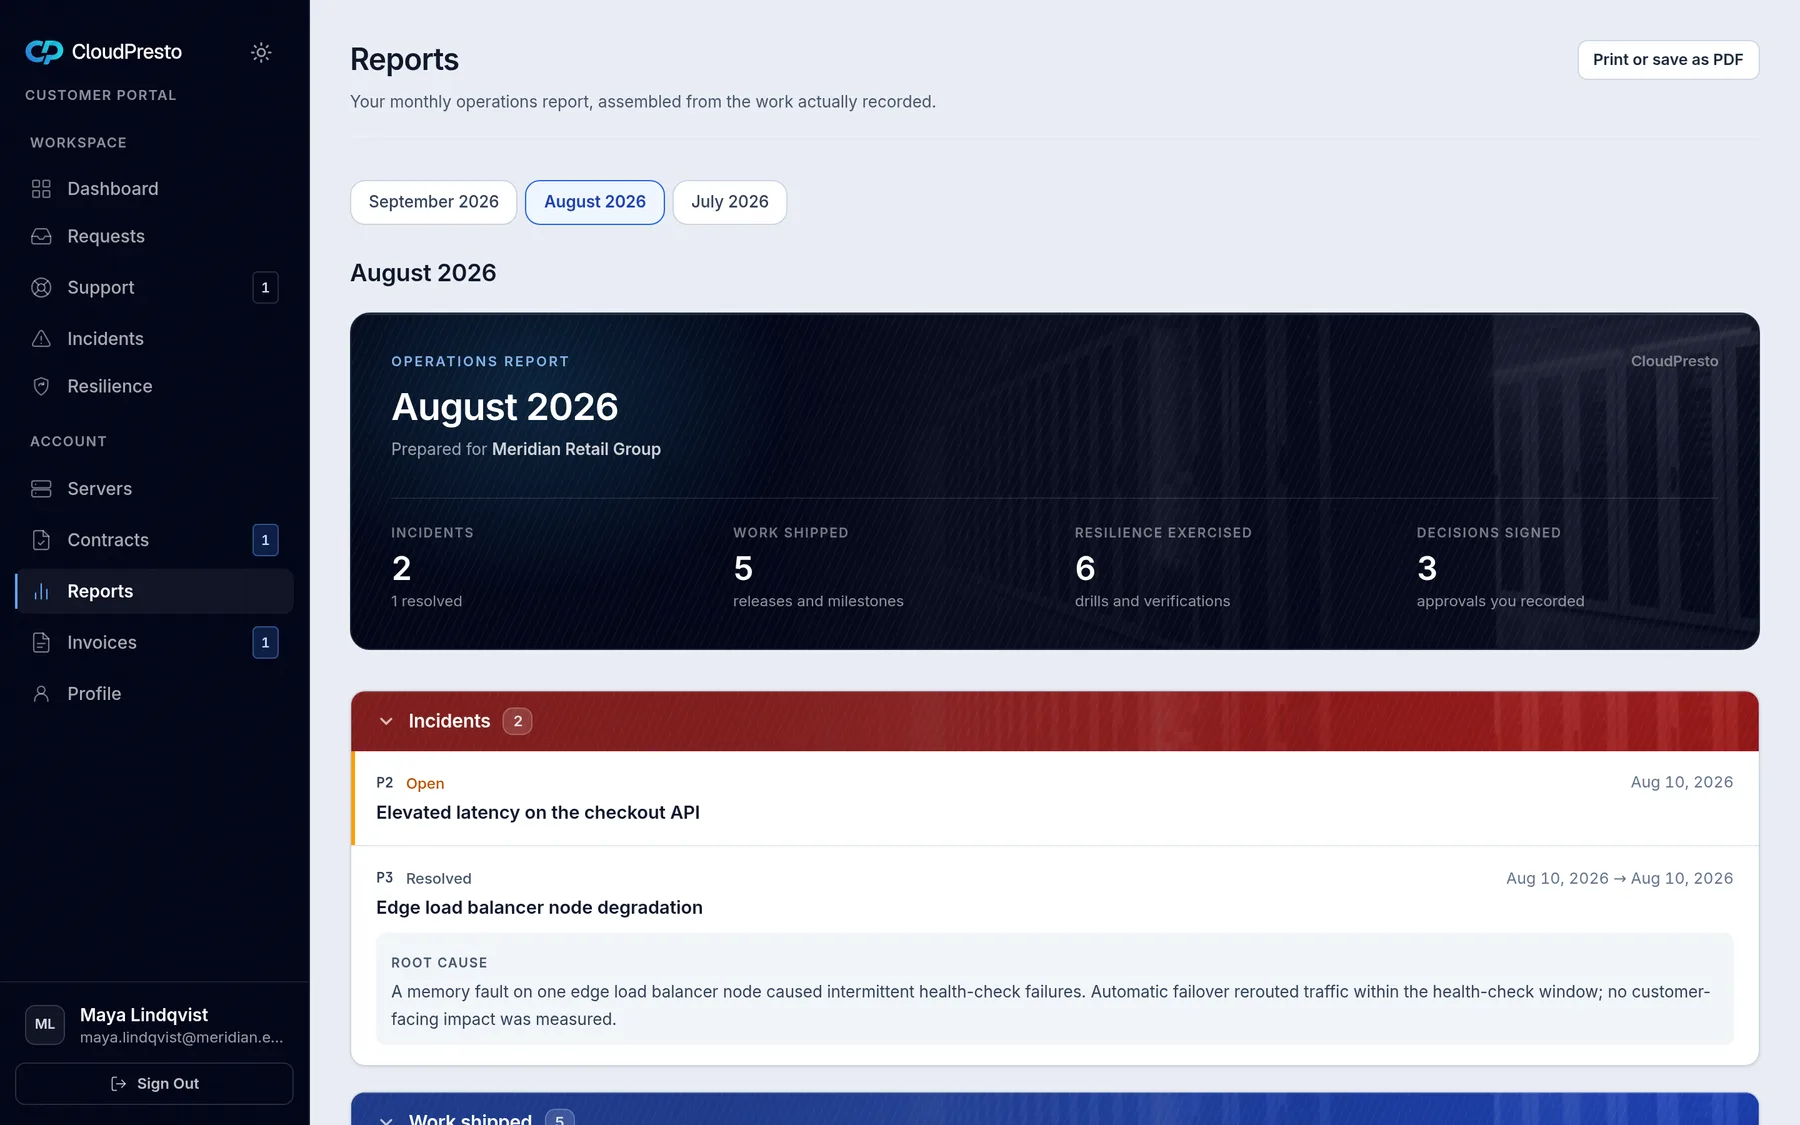
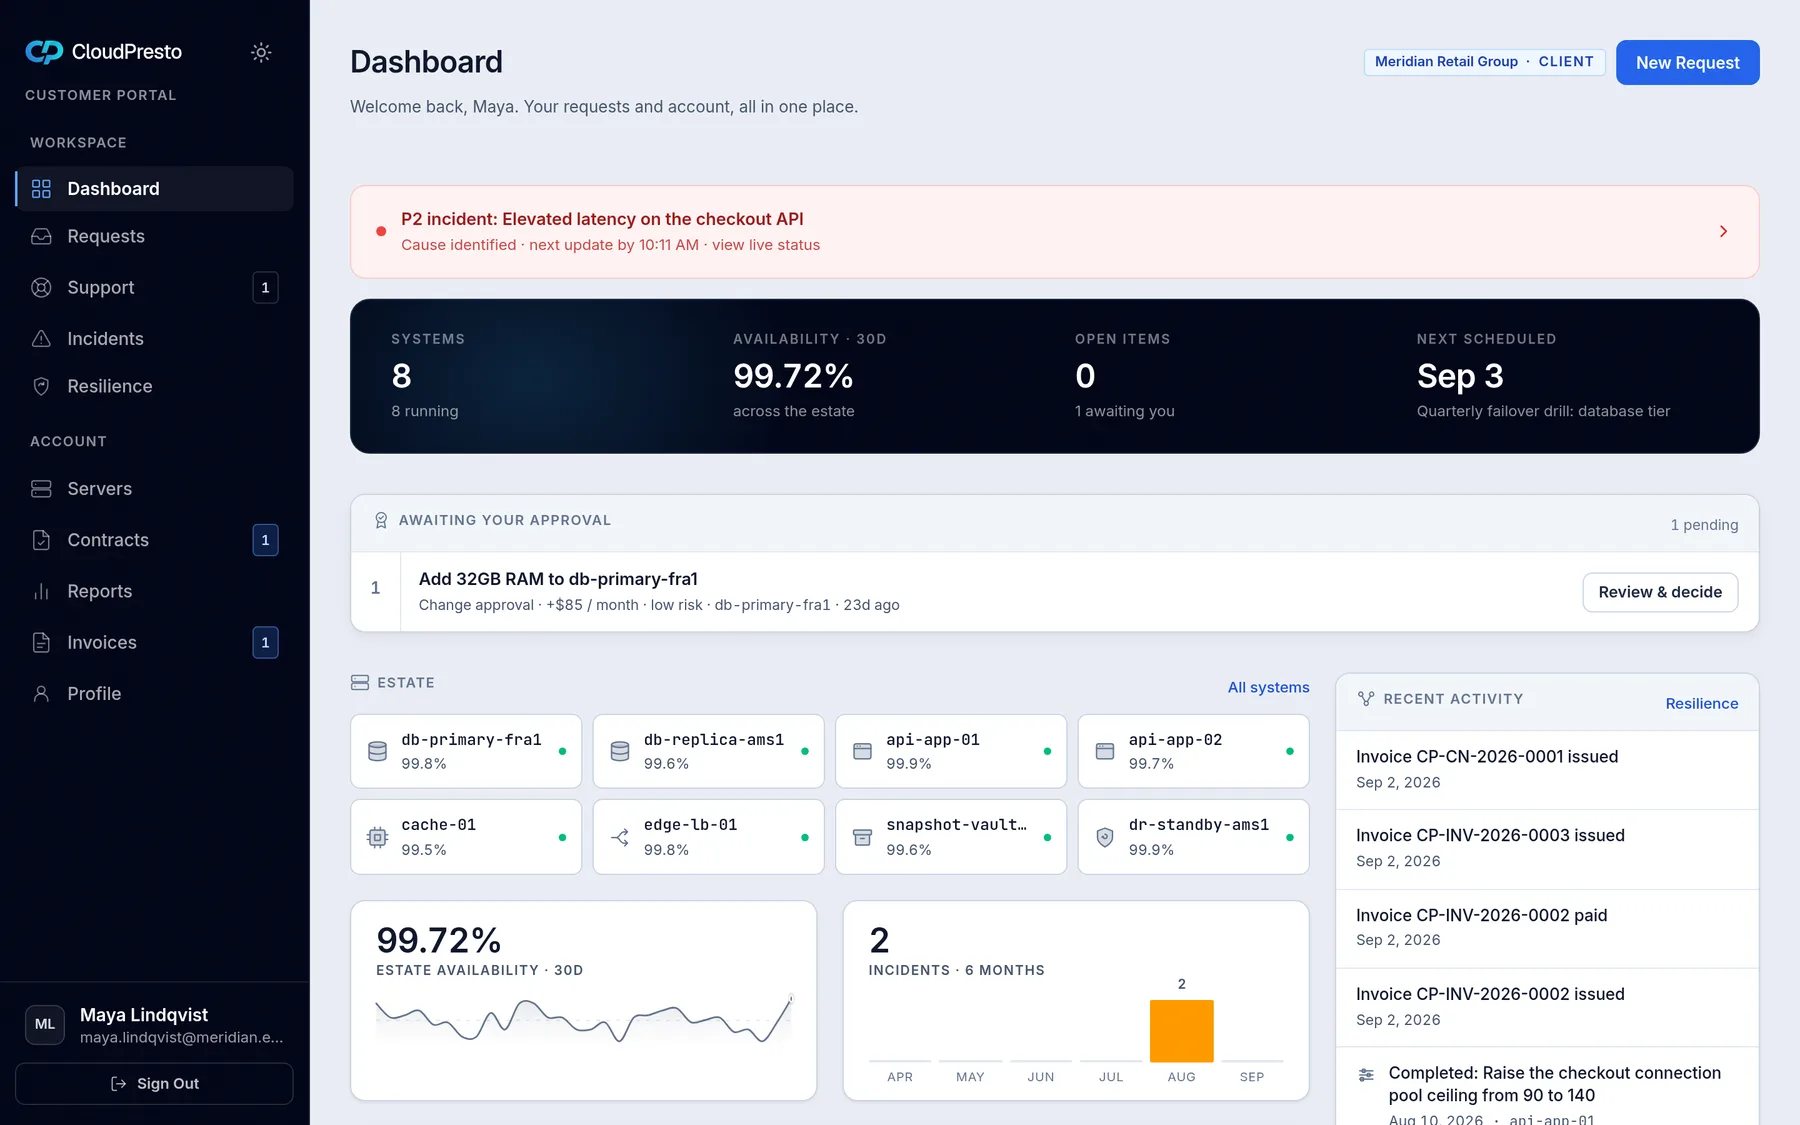
Exhibit B · The portal, live
Five real screens from the client portal on our demo estate, with numbered points on each. Press Play, or step through.
01 · Dashboard · 1 of 4
The incident, on the front page
Severity, what we found, and the time of the next update. The same status we work from, not a summary written for you afterwards.
Captured on our demo estate (Meridian Retail Group); persona name shown.
Exhibit C · The monthly report
Assembled from the work recorded in your portal that month and delivered there, for your leadership to read in one sitting.
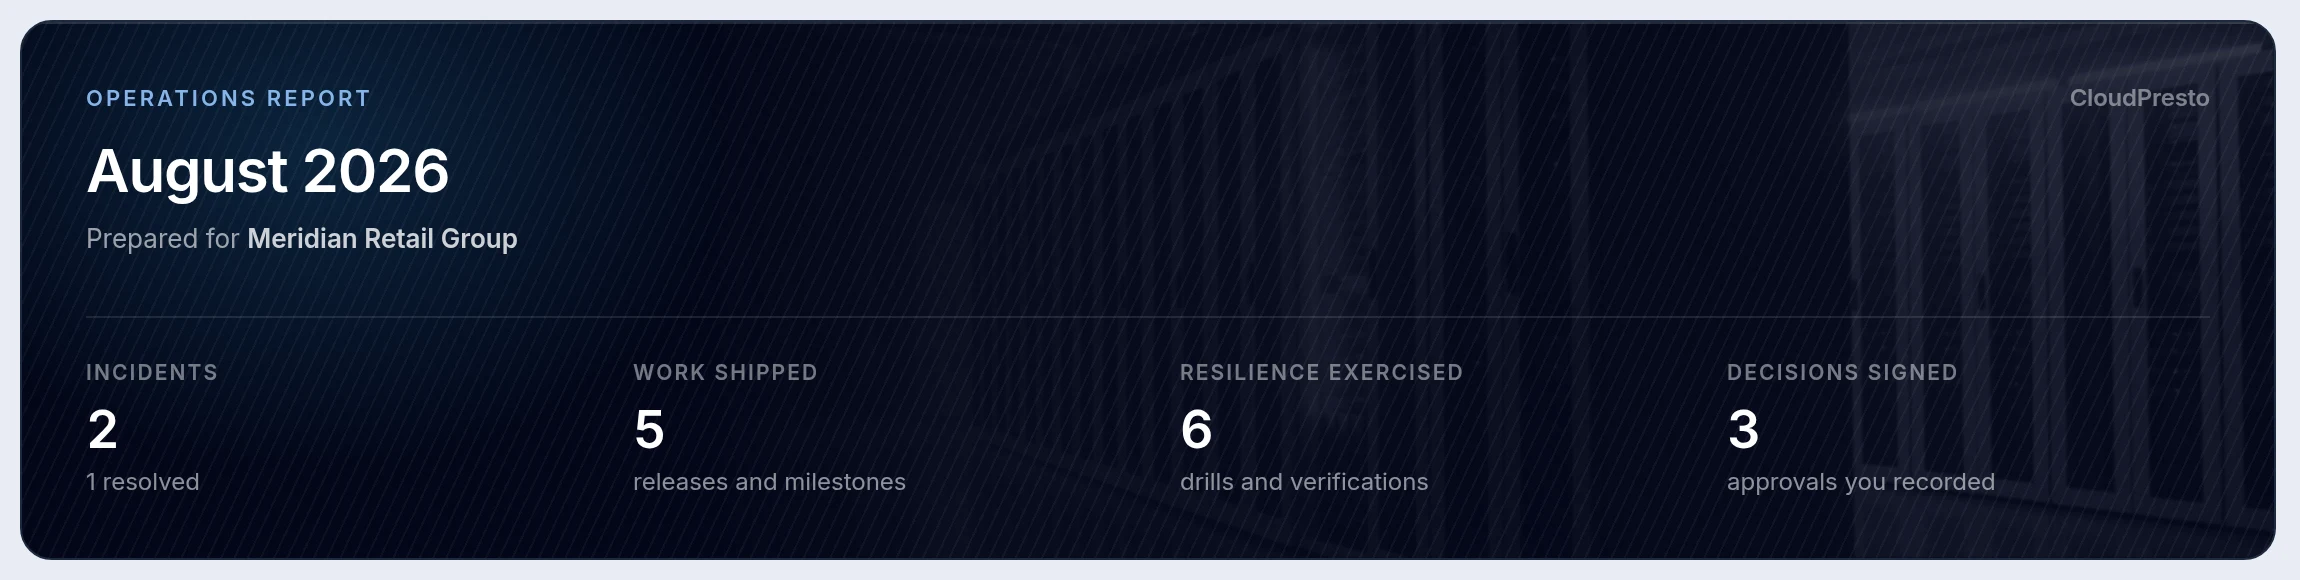
uptime · incidents · changes · drills · what we harden next
Operational specificationsThe report header, as delivered in the portal. Shown on our demo estate.
Exhibit D · A product we built and run
An edge-cached React app with an isolated API origin, PostgreSQL and Redis behind it, Cloudflare WAF in front. When one creator posts and thousands hit the same wall within minutes, the edge absorbs the surge. Behind that: zero-downtime releases and database snapshots with restore drills.
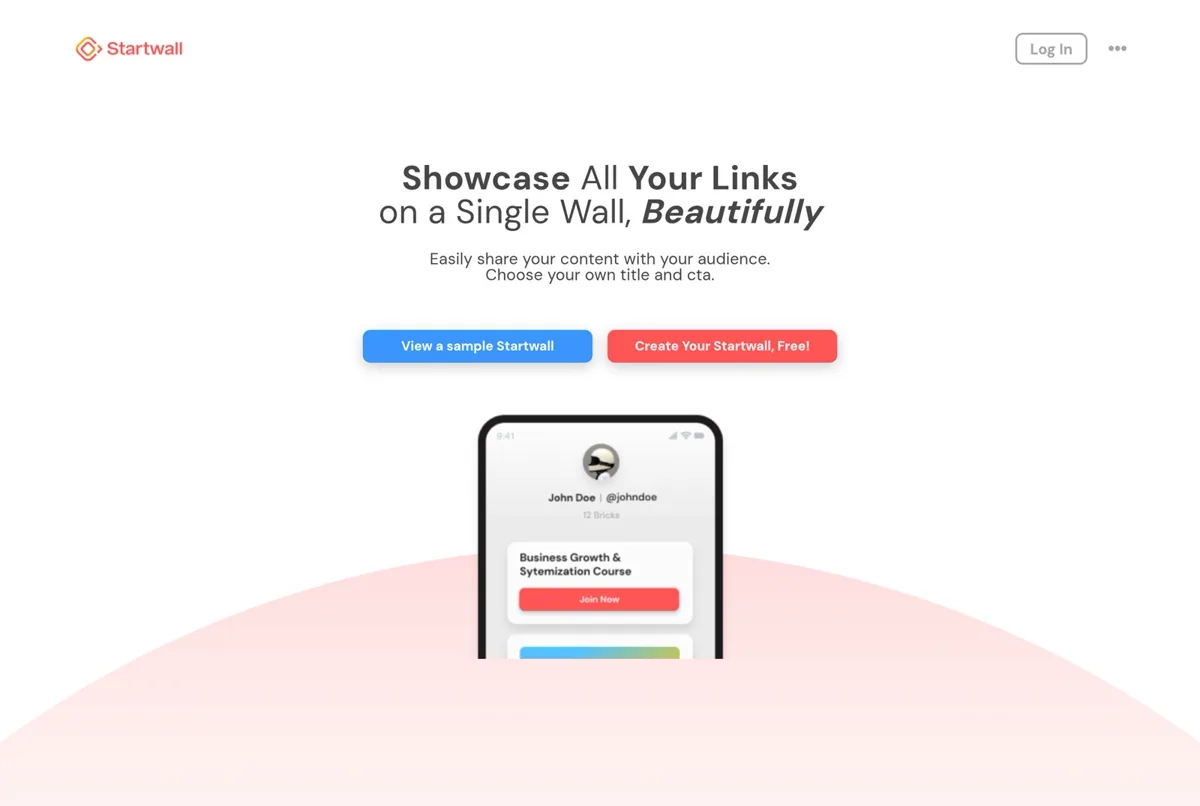
Startwall in production. Designed, built, and operated by CloudPresto.
This is the floor for every system we run. Across the industry, it's sold as an add-on.
In every package
Every copy proves itself: restore verification runs against real snapshots, so the backup you count on is known to be complete.
3
copies of your data, always.
2
different storage systems, so one class of failure can't touch both.
1
copy held offsite, outside the blast radius of the primary.
+1
georedundant copy on another continent. A region can burn down and your data has an alibi.
The floor
Three copies on two storage systems, one held offsite, one on a second continent, and a restore verified against real snapshots. The minimum under every package.
Delivery, runtime, operations, and reporting are stations on the same line. Bring a workload, or bring an idea and we build it with you first. Open a station for its specification.
Everything above, in every one
Managed Core
For smaller production estates that need a real service team.
What is includedGrowth + Continuity
Most PopularFor customer-facing systems where continuity and visibility matter.
What is includedMission-Critical
For regulated, hybrid, or multi-team estates needing executive reporting.
What is includedTiers scale the workloads, the hours, and the depth. Contractual SLAs available on request.
The ask
Every engagement starts as a working session on your actual environment. Pick the conversation that fits, and you leave it with a clear read, whether or not we ever run it.
Your failure modes and recovery posture, on your actual environment.
A working session on the architecture of what you are building or changing.
Our security posture and practices, to the specifics your team or auditors need.
What is moving, what worries you, and a cutover plan you can reverse.
Scope an application, an API, or a modernization with the team that will run it.
Four taps, and you see what the session would put on the table.
Preview your review
01 / 04
What shape is the workload?
Controls aligned with SOC 2, ISO 27001, and CIS. Encryption in transit and at rest, customer-managed keys, audit trails, and data residency by region. Security posture in full →